#software #ai #llm #open-source
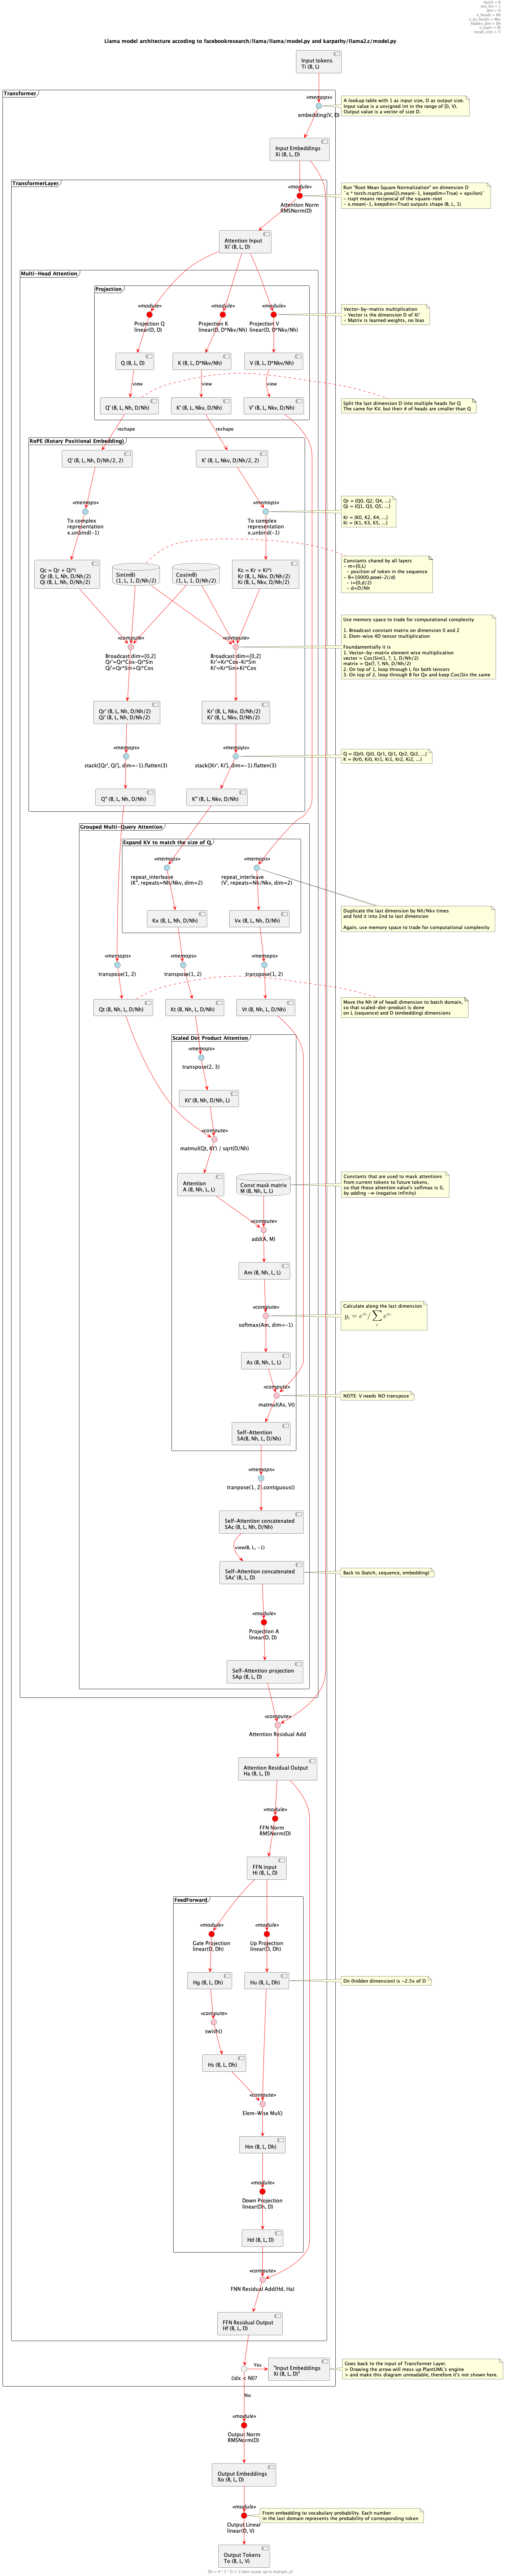
Here I’m capturing the details of llama’s model architecture use PlantUML component diagram, using the following 2 GitHub repos as references
- https://github.com/facebookresearch/llama/blob/main/llama/model.py
- https://github.com/karpathy/llama2.c/blob/master/model.py
In the following diagram
- The “gray boxes” are tensors with their shapes in parentheses
- The “colored round dots” are operations with their categories include
- “memops”: memory operations
- “module”: PyTorch module operators
- “compute”: non-PyTorch computational operators
- The “grouping boxes” are to make the architecture modularized close to the original source code
- The “yellow boxes” are my in-depth comments and understanding of different parts of the architecture
In order to make the diagram more readable, here I choose to use abbreviations of parameters and hyper-parameters, which are explained on the upper-right corner of the diagram.
NOTE: this architecture diagram doesn’t include KV cache support, which will be explained in the next part.
You can find the source of this diagram at https://github.com/jimwang99/understanding-llama2/blob/main/model.puml